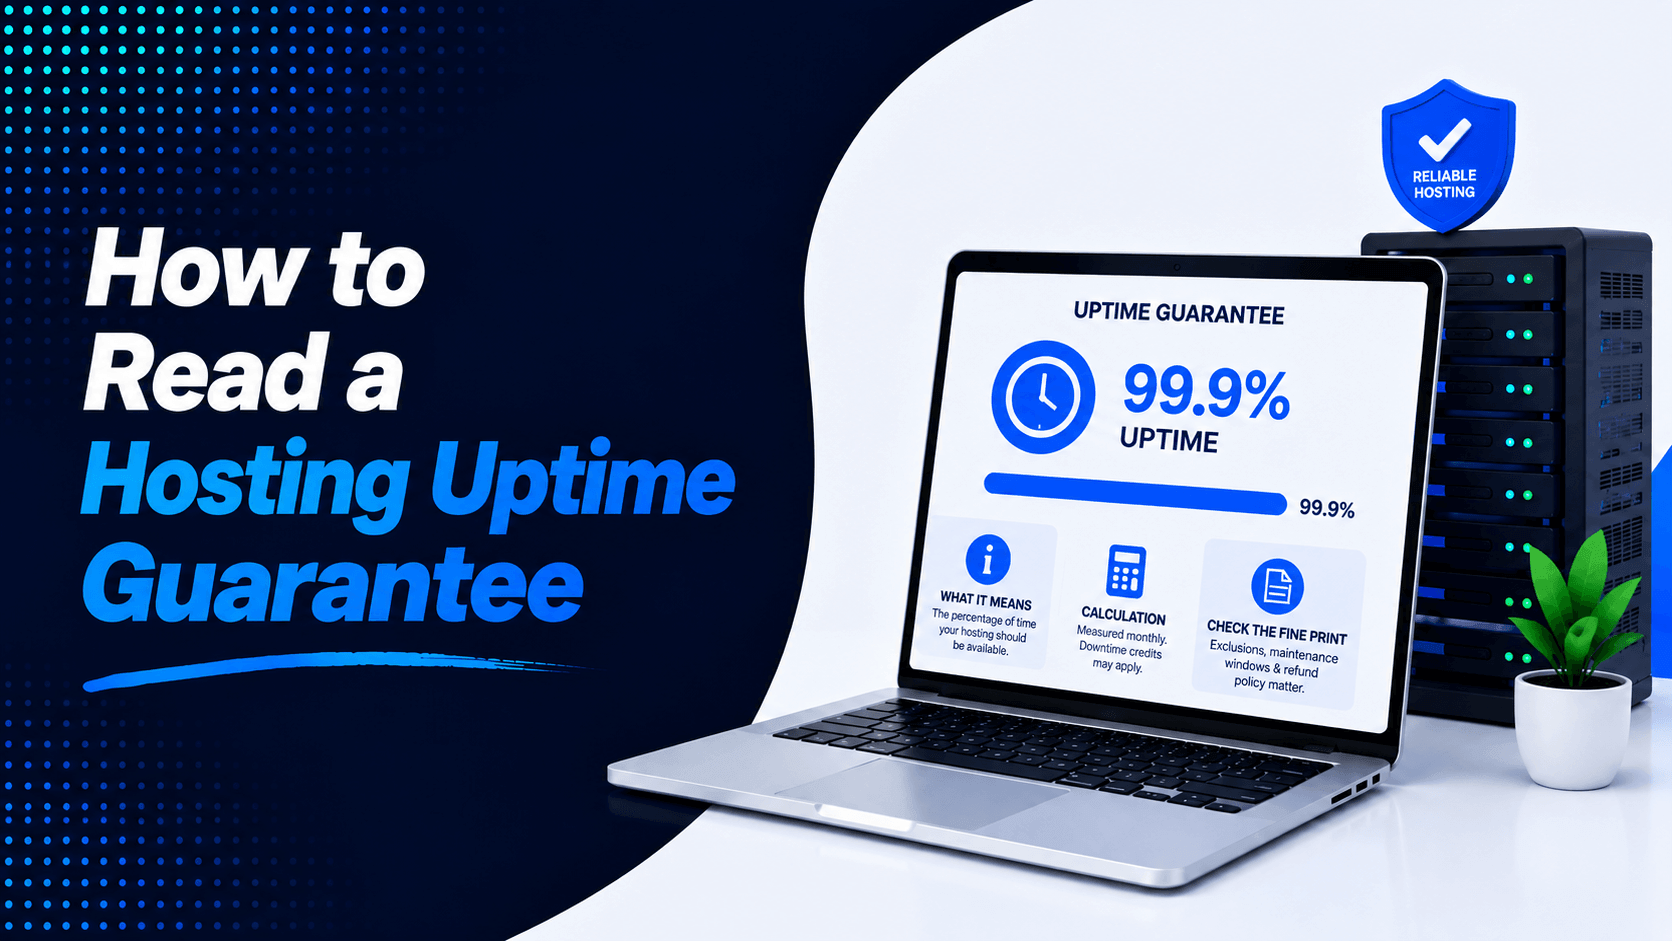
When you compare hosting plans, one promise shows up again and again: 99.9% uptime. It sounds strong. It sounds safe. It sounds close to perfect.
For a business site, blog, store, or service site, website uptime matters a lot. If your site goes offline, visitors leave. Sales can stop. Trust can drop. Search visibility can also suffer when users cannot reach your pages.
But the number on the sales page is only the headline.
Many hosting companies promote a high hosting uptime guarantee. Yet the real limits sit inside the Service Level Agreement (SLA). Planned maintenance may be excluded. Third-party failures may be excluded. Credits may be small. In many cases, you must file the claim yourself.
This guide explains how to read a hosting uptime guarantee. It shows how downtime is counted. It reveals what the fine print often hides. It also helps you judge hosting reliability before you buy.
What does a hosting uptime guarantee really mean?
A hosting uptime guarantee is the share of time a provider says its service should stay available during a set period, usually a month.
If a host promises 99.9% uptime, it is not saying your site will never fail. It is saying some downtime is still allowed. The higher the percentage, the less downtime is allowed. That is the basic idea.
For example:
- 99% uptime allows much more downtime.
- 99.9% uptime cuts that time down a lot.
- 99.99% uptime is far stricter and is usually linked to stronger infrastructure.
- 100% uptime is mostly a marketing phrase. It is only real if the provider has deep redundancy and very costly systems behind it.
It is also important to know what the host is measuring. In many cases, the promise is about server or network availability. It is not about whether your full website works well for real users.
How is uptime calculated?
The math is simple.
Uptime Percentage = (Total Time − Downtime) ÷ Total Time × 100
If your site is unavailable for 30 minutes in a 30-day month, the uptime for that month is:
(43,200 − 30) ÷ 43,200 × 100 = 99.93%
That sounds great. But even this number can hide a problem. A server can look “up” while your site is slow, broken, or failing for visitors. Some providers measure service at the network level, not at the page level.
Here is the real-world impact of common uptime targets:
| Uptime Guarantee | Possible Downtime Per Year | Per Month |
|---|---|---|
| 99% | ~3.65 days | ~7.2 hours |
| 99.9% | ~8.76 hours | ~43.2 minutes |
| 99.99% | ~52.6 minutes | ~4.3 minutes |
| 99.999% | ~5.26 minutes | ~26 seconds |
These figures show why small changes in percentage matter more than they seem at first glance.
The guaranteed number is the promise. Actual uptime is what you and your visitors really see.
The hidden meaning behind “99.9% uptime”
There is a reason so many hosts use 99.9% uptime in their marketing. It is simple to understand, common in the market, and good enough to sound reassuring.
But the number alone does not tell you how your site will feel day to day.
A host can hit its uptime target while users still deal with problems. They may face failed page loads. They may experience route issues. DNS trouble can occur. Plugin crashes happen. App errors appear. Service gaps may arise during maintenance windows. The provider may still say the core service stayed within target. Your visitors will not care about that distinction. They will only see that the site did not work when they needed it.
So when you read 99.9% uptime guaranteed, ask a better question:
What exactly counts as downtime, and what does not?
Read the fine print: what hosting companies do not highlight
The most important part of any uptime promise is usually the part most buyers never read.
The SLA is where the real rules live. That is where you learn what the host measures. That is where you learn what they exclude. That is where you learn how credits work. That is also where you learn how fast you must act if you want compensation.
Scheduled maintenance exclusions
Most providers do routine maintenance. That can include:
- security updates
- hardware swaps
- operating system patches
- network work
This is normal. The issue is that many hosts do not count planned maintenance as downtime under the guarantee. One published SLA states that if notice is given ahead of time, the outage does not qualify for credit at all.
That means your site can still go dark during an important sales window, yet the host may say it did not break the uptime promise.
Third-party problems
Many SLAs also remove blame for issues outside the host’s direct control.
That often includes things like upstream network failures. It includes backbone congestion. It includes outside software issues, plugins, APIs, and other third-party services. Some providers also exclude malicious attacks and force majeure events. In plain English, that means many common outage causes may never count toward your claim.
From your side, the website was down. From the provider’s side, it may be marked as excluded.
Your own website issues
Even when the server stays online, your website can still fail.
A bad plugin can crash WordPress. Broken code can overload resources. A damaged database can take pages offline. A traffic spike can push you past the limits of a cheap plan. In many SLAs, those problems are your responsibility, not the host’s.
So the server may be “available” while your actual site is not.
Understanding the uptime SLA
A sales page makes a promise. The SLA defines the legal version of that promise.
That difference matters.
Marketing promise
This is the line used to sell the plan.
Example:
99.9% uptime guaranteed
Legal SLA
This is where you learn:
- how uptime is measured
- what counts as downtime
- what is excluded
- what credit you may receive
- how long you have to file a claim
That last point is easy to miss. In one public SLA example, the customer must open a ticket within five business days. In AWS, the claim must be submitted by the end of the second billing cycle after the incident. The customer must also provide logs and outage details.
What happens if the host misses the target?
Usually, you do not get cash back for lost business. You get service credits.
Those credits are often limited to future billing. They may also be capped. One provider says the credit cannot exceed the monthly renewal price of the service. AWS says credits are applied against future payments and are the sole remedy under that SLA.
A real SLA example from AWS looks like this:
| Monthly Uptime Percentage | Service Credit |
|---|---|
| Less than 99.99% but at least 99.0% | 10% |
| Less than 99.0% but at least 95.0% | 30% |
| Less than 95.0% | 100% |
That table shows an important truth. Even when the provider misses the target, the payout is usually tied to your hosting fee, not to your lost revenue.
What should you watch for in the fine print?
- Measurement method: Is the host checking ping only, or real page delivery?
- Maintenance policy: Is planned work excluded?
- Claim rules: Do you need logs, timestamps, and a support ticket?
- Payout cap: Is the credit limited to one month of service?
- Remedy type: Do you get credit only, not a refund?
An SLA is only useful if you understand it before anything goes wrong.
How hosting providers calculate downtime
Not all uptime monitoring works the same way. That is a big reason why your experience may differ from the provider’s report.
Common monitoring methods
Providers and monitoring tools use several methods:
- Ping monitoring checks if a server responds at all.
- HTTP/HTTPS monitoring checks whether a web request returns a valid response.
- Keyword checks can test whether important content appears on the page.
- Response time monitoring tracks how long the server takes to answer.
A ping check is better than nothing, but it does not prove your site is healthy. A server can reply to a ping while the website app is broken. An HTTP check is stronger, but it still may only test one page.
Internal monitoring has another issue. The provider controls both the measurement and the report. That does not always match what your visitors see in the real world.
Why method matters
If a host tracks network reachability, it may report high uptime. Yet users may face blank pages, timeout errors, or broken app behavior.
That is why outside checks matter. Good monitoring should test what users actually reach. It should not just check whether the machine is powered on.
Common uptime guarantee tricks
Some web hosting uptime claims are less helpful than they look.
“Guaranteed” but hard to claim
A guarantee sounds strong until you try to use it.
Some SLA models make the customer do all the work. You may need to monitor your own site. You may need to record the outage. You may need to collect timestamps. You may need to submit the ticket on time. Then you wait while the provider decides whether the event qualifies.
If the process is hard, fewer people claim the credit.
Tiny credits
Even when a claim is approved, the credit may be much smaller than the damage caused by the outage.
If your store loses sales during downtime, the SLA usually does not cover that loss. It only covers a slice of your hosting bill, and often only as future account credit.
Broad exclusions
This is the biggest trick of all.
Many public SLA examples exclude planned maintenance. They exclude emergency work. They exclude customer actions. They exclude outside services. They exclude attacks. They exclude traffic spikes. They exclude force majeure events. Once those exceptions are removed, much less downtime may qualify than you expected.
That is why a large uptime number is not enough on its own.
Uptime and website performance are not the same
A site can be online and still feel broken.
If pages take too long to load, users leave. They do not care that the server answered with a status code. They care that the page was slow.
TTFB matters
TTFB stands for Time to First Byte. It measures how long it takes from the start of a request until the first byte of the response arrives. Google’s web.dev guide says most sites should aim for about 0.8 seconds or less. Chrome’s Lighthouse documentation flags slow server response times when the wait goes beyond 600 ms for the main document.
A slow server response time can come from weak app logic. It can come from heavy database work. It can come from not enough CPU or memory. It can come from network delay. A CDN can also help reduce latency.
Resource limits matter too
A host can advertise 99.9% uptime and still give you limited CPU, memory, or process capacity. If your site hits those limits, it may crawl, fail, or throw errors while the provider still marks the service as “up.”
That is why hosting reliability is not only about uptime. It is also about speed, resources, and stability under load.
How to verify a hosting provider’s real uptime
Do not rely only on the sales page.
Use outside checks.
Use uptime monitoring tools
Independent tools can watch your site from outside your host’s network.
Popular options include UptimeRobot, Pingdom, and StatusCake. These services can check availability, track response time, alert you when a site fails, and in some cases show public status history.
Check long-term records
A perfect 30-day window does not prove much.
You want a longer pattern. Review status pages, outside monitoring history, and real customer feedback. Look for repeat complaints about outages, slow support, or hidden SLA limits.
Test before moving everything
If possible, run a test site on the new host first.
Monitor it for a few weeks. Compare response time, alerts, and stability. Real data beats a marketing claim every time.
Questions to ask before buying hosting
Before you choose a provider, ask clear questions.
Is uptime measured by the host or by a third party?
Self-reported data is useful, but outside monitoring is more trustworthy. If the host cannot show independent proof, be careful.
What counts as downtime?
Does a failed page count? Does a 500 error count? Do DNS failures count? If the definition is too narrow, the guarantee is weaker than it looks.
Is maintenance excluded?
Ask how much notice you get. Ask how often maintenance happens. Ask whether it can affect peak business hours.
What compensation do I really get?
Ask whether the remedy is a refund or only service credit. Ask whether the credit is capped. Ask whether you must request it yourself.
How good is support during an outage?
A fast answer matters. A real fix matters more.
Also ask whether the company gives public updates during incidents. Silence during downtime is a bad sign.
Uptime guarantee differences by hosting type
Not all hosting plans carry the same risk.
Shared hosting
Shared hosting is usually the cheapest option. It often comes with standard uptime language. But resources are shared with other sites. That means one noisy account can affect performance for others.
VPS hosting
VPS hosting usually gives you better isolation. It gives you more stable resources. That can lead to stronger performance. That can lead to more predictable uptime than entry-level shared plans.
Cloud hosting
Cloud hosting often uses distributed systems and failover design. That makes it easier to keep service running when one node fails. Strong cloud SLAs also tend to define credits more clearly.
Dedicated hosting
Dedicated hosting gives you the most control. But it also puts more responsibility on setup and management. Hardware quality matters. Replacement speed matters. Support quality matters as much as the uptime number.
Real factors that improve website availability
A promise alone does not keep a site online.
What helps most is solid setup:
- strong server infrastructure
- automatic backups
- CDN use where it makes sense
- outside uptime monitoring
- good security
- regular updates
- smart caching
- enough CPU, RAM, and disk performance
These things do more for real uptime than a bold sales line ever will. Google’s performance guidance also points to faster app logic. It points to better database work. It points to stronger hardware. It points to CDN use as direct ways to improve server response time.
Final checklist: choosing hosting for reliability
Before you buy, remember this:
- Do not choose a host based only on a 99.9% uptime badge.
- Read the SLA from start to finish.
- Check what is excluded.
- Check how claims work.
- Check whether credits are small or capped.
- Compare speed, not just availability.
- Use outside monitoring to verify the truth.
- Match the hosting type to your site’s needs.
Conclusion
A hosting uptime guarantee is useful. But it is only one part of the story.
A 99.9% uptime promise may sound strong. Yet the real experience depends on other factors. It depends on how uptime is measured. It depends on what the SLA excludes. It depends on how fast support reacts. It also depends on whether your site performs well under normal traffic.
So read past the headline. Check the fine print. Verify the host with outside tools. If you do that, you will make a better choice. You will protect your traffic. You will give your visitors a more stable experience.
Leave a Comment